On-Device SLM Deployment: 70-Billion Parameter Models Offline
Advertisements
On-device SLM deployment enables 70-billion parameter quantized models to run entirely offline, delivering unprecedented privacy, speed, and reliability for advanced AI applications at the edge.
The landscape of artificial intelligence is rapidly evolving, with a transformative shift towards localized processing. The ability to achieve on-device SLM deployment, specifically running 70-billion parameter quantized models completely offline, represents a monumental leap forward, promising to redefine how we interact with AI.
The Dawn of Offline AI: Why On-Device Matters
The conventional paradigm of AI relies heavily on cloud computing, where powerful data centers process complex models. While effective, this approach introduces latency, privacy concerns, and a dependency on constant internet connectivity. On-device SLM deployment, particularly for large models, addresses these limitations head-on, ushering in an era of truly autonomous and responsive AI.
Running sophisticated AI models directly on user devices—be it a smartphone, a smart appliance, or an industrial sensor—unlocks a new realm of possibilities. It means personalized AI experiences that are always available, regardless of network conditions, and data processing that remains private to the user. This shift is not merely an optimization; it's a fundamental change in AI architecture.
Breaking Free from the Cloud
The traditional cloud-centric model, while powerful, inherently carries certain drawbacks. Data must travel to and from remote servers, creating potential bottlenecks and security vulnerabilities. For many critical applications, such as autonomous driving or medical diagnostics, real-time response and stringent data privacy are paramount.
- Reduced Latency: Instantaneous processing without network delays.
- Enhanced Privacy: Data remains on the device, never leaving the user's control.
- Improved Reliability: AI functions uninterrupted, even without internet access.
- Lower Operational Costs: Less reliance on cloud infrastructure reduces expenses.
The implications of moving AI processing to the edge are far-reaching, enabling new applications and improving existing ones across various industries. This foundational change is paving the way for more robust and user-centric AI systems.
Understanding Quantization: The Key to Compact Models
Deploying massive 70-billion parameter models on resource-constrained devices seems like a paradox. The magic behind this feat lies in a technique called quantization. Quantization is a process that reduces the precision of the numbers used to represent a neural network's weights and activations, thereby shrinking its memory footprint and computational requirements without significantly sacrificing accuracy.
Traditionally, neural networks operate using 32-bit floating-point numbers. Quantization often converts these to 8-bit integers, or even lower, significantly reducing the amount of data that needs to be stored and processed. This compression is crucial for fitting large models onto devices with limited memory and processing power, making on-device SLM deployment feasible.
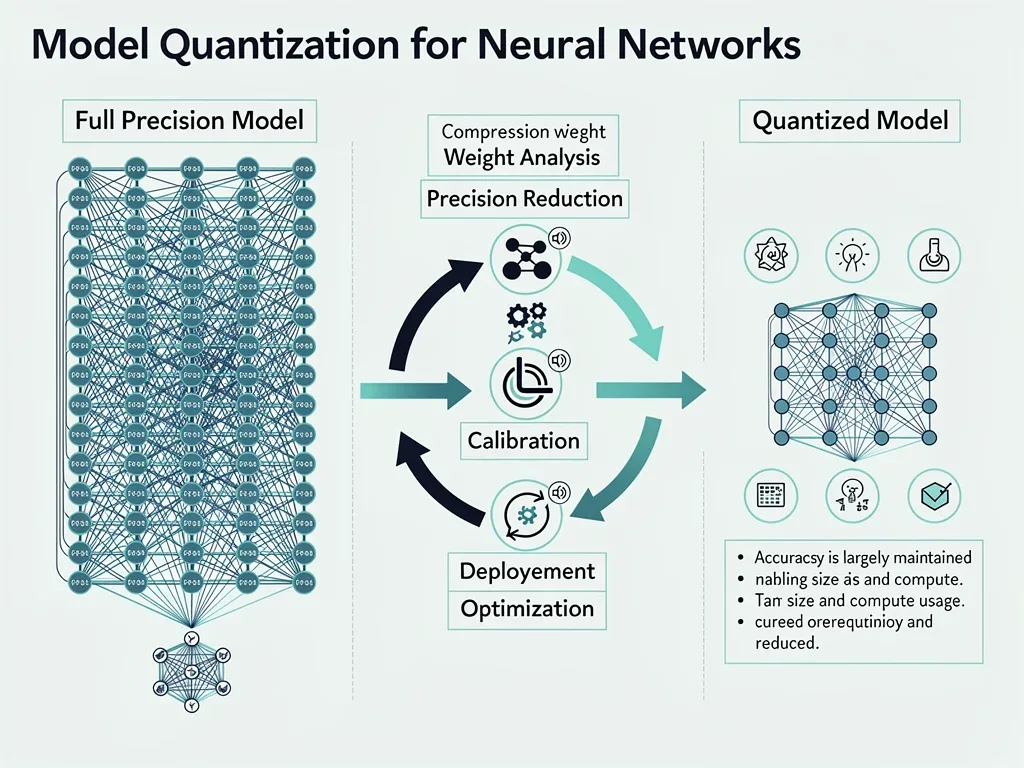
The process involves mapping a range of floating-point values to a smaller set of integer values. While this might sound like it would lead to a loss of information, advanced quantization techniques are designed to minimize this impact, ensuring that the model's performance remains largely intact for its intended tasks.
Techniques and Trade-offs
Various quantization techniques exist, each with its own trade-offs between model size, inference speed, and accuracy. Post-training quantization (PTQ) applies quantization after the model has been fully trained, offering a simpler workflow. Quantization-aware training (QAT), on the other hand, integrates quantization into the training loop, often yielding better accuracy by allowing the model to adapt to the reduced precision.
- Post-Training Quantization (PTQ): Simpler, faster to implement, but can have a larger accuracy drop.
- Quantization-Aware Training (QAT): More complex, requires re-training, but generally achieves higher accuracy.
- Mixed-Precision Quantization: Uses different bit-widths for different layers based on sensitivity.
The selection of the appropriate quantization strategy is critical and often depends on the specific model, the target device's capabilities, and the acceptable accuracy degradation. This meticulous process is what enables the impressive feat of running 70-billion parameter models locally.
Challenges and Innovations in Offline Deployment
While the benefits of offline AI are clear, achieving robust on-device SLM deployment for models of this magnitude presents significant technical hurdles. These include managing computational resources, optimizing power consumption, and ensuring the model remains performant despite reduced precision. Developers are constantly innovating to overcome these challenges.
One major challenge is memory management. Even with quantization, a 70-billion parameter model still requires substantial memory. Innovations in memory-efficient architectures, dynamic memory allocation, and efficient data loading strategies are crucial. Furthermore, specialized hardware accelerators, such as neural processing units (NPUs) found in modern smartphones, are becoming indispensable for handling the intensive computations efficiently.
Hardware Acceleration and Software Optimization
The symbiotic relationship between hardware and software is key to successful on-device deployment. Dedicated AI chips are designed to accelerate matrix multiplications and convolutions, the core operations of neural networks. On the software front, highly optimized inference engines and frameworks are developed to leverage these hardware capabilities to their fullest.
- Neural Processing Units (NPUs): Specialized hardware for AI workloads.
- Optimized Inference Engines: Software libraries like ONNX Runtime, TFLite, and Core ML.\
- Memory-Efficient Architectures: Model designs that minimize memory footprint.
These combined efforts ensure that even complex models can execute inferences at speeds suitable for real-time applications, all while minimizing power drain, which is vital for battery-powered devices. The continuous advancement in both hardware and software is what truly pushes the boundaries of what's possible for offline AI.
The Impact on Privacy and Security
One of the most compelling advantages of on-device SLM deployment is the profound impact on user privacy and data security. When AI models process data locally, sensitive information never leaves the device, eliminating the need to transmit it to external servers. This intrinsic privacy-by-design approach is a significant differentiator from cloud-based AI.
In an era where data breaches and privacy concerns are paramount, keeping personal data on the device offers a robust layer of protection. This is particularly relevant for applications dealing with highly sensitive information, such as health records, financial transactions, or personal communications. Users gain greater control and assurance that their data remains private.
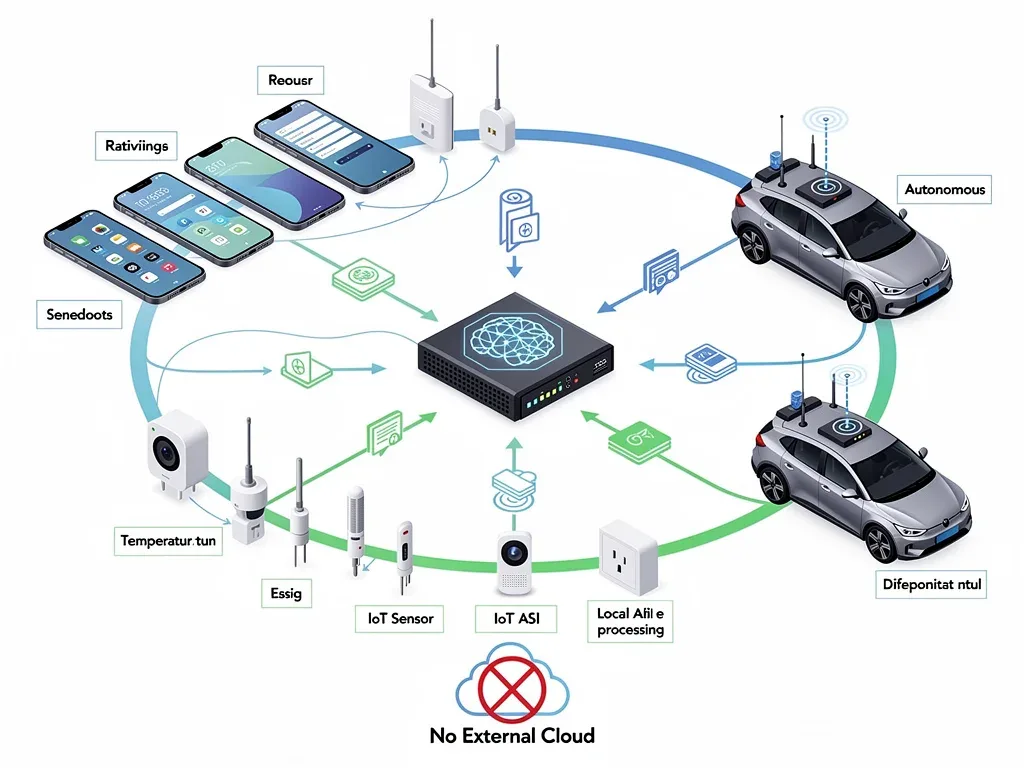
Beyond privacy, security is also enhanced. The attack surface is reduced when data isn't constantly traveling across networks. While on-device models can still be vulnerable to certain types of attacks, the fundamental reduction in data exposure significantly strengthens the overall security posture of AI applications.
Building Trust Through Local Processing
For many consumers and enterprises, trust is a critical factor in adopting new technologies. The ability to ensure that personal or proprietary data is processed locally, without being uploaded to potentially vulnerable cloud servers, builds immense trust. This trust can accelerate the adoption of AI in sensitive domains.
- Data Sovereignty: Users retain full control over their data.
- Reduced Attack Surface: Less data transmission means fewer interception points.
- Compliance with Regulations: Easier adherence to privacy laws like GDPR and CCPA.
The move towards offline AI is not just a technical advancement; it's a strategic one that aligns with growing societal demands for greater data privacy and security. This paradigm shift will likely become a standard expectation for many future AI applications.
Use Cases and Future Applications
The ability to run 70-billion parameter quantized models completely offline unlocks a vast array of new and improved use cases across diverse sectors. From highly personalized experiences on smartphones to robust industrial automation, the implications are revolutionary. The real-time, private, and reliable nature of on-device AI will drive innovation.
Consider advanced voice assistants that understand complex commands and context without sending audio to the cloud, or intelligent cameras that perform sophisticated object recognition and scene analysis directly at the source. In healthcare, portable diagnostic tools could offer immediate insights without compromising patient data. The possibilities are truly extensive.
Transforming Industries with Edge AI
Industries such as automotive, manufacturing, retail, and healthcare stand to benefit immensely from the widespread adoption of on-device SLM deployment. Autonomous vehicles, for instance, require instantaneous decision-making based on sensor data, a task ideally suited for edge processing.
- Smartphones: Advanced language processing, personalized content generation, intelligent assistants.
- Automotive: Real-time perception, predictive maintenance, enhanced driver assistance systems.
- Industrial IoT: Anomaly detection, predictive analytics, process optimization at the factory floor.
- Healthcare: Portable diagnostics, personalized patient monitoring, secure data analysis.
These applications underscore the practical and economic advantages of deploying powerful AI models directly where the data is generated and actions need to be taken. The future will see more intelligence embedded into everyday objects and critical infrastructure.
The Road Ahead: Scaling and Accessibility
While significant progress has been made in on-device SLM deployment, the journey towards widespread adoption and maximum accessibility is ongoing. Future developments will focus on further optimizing quantization techniques, developing even more efficient hardware, and creating user-friendly tools that democratize the deployment process. The goal is to make these powerful models accessible to a broader range of developers and devices.
Research continues into novel quantization methods that can achieve even higher compression ratios with minimal accuracy loss. Furthermore, the design of future System-on-Chips (SoCs) will increasingly prioritize integrated AI accelerators, making high-performance edge AI a standard feature rather than a specialized capability. This will lower the barrier to entry for developers and manufacturers alike.
Democratizing Advanced AI
The ultimate vision for on-device AI is to democratize access to advanced intelligence. By enabling powerful models to run on affordable, ubiquitous devices, AI capabilities can reach a much wider audience, fostering innovation and creating new opportunities. This involves not only technical advancements but also the development of robust ecosystems.
- Standardized Frameworks: Easier model conversion and deployment across platforms.
- Developer Tools: Intuitive SDKs and APIs for integrating edge AI into applications.\
- Community Collaboration: Sharing best practices and open-source contributions.
The continuous evolution in these areas will ensure that the promise of offline, on-device AI is fully realized, transforming the way we live, work, and interact with technology on a daily basis. The future of AI is undeniably local, private, and always available.
| Key Point | Brief Description |
|---|---|
| Offline Operation | Enables AI models to function without internet, reducing latency and cloud dependency. |
| Quantization | Technique to reduce model size and computational demands, making 70B models feasible on devices. |
| Enhanced Privacy | Data processing occurs locally, ensuring sensitive information never leaves the user's device. |
| Broad Applications | Transforms industries from smartphones and automotive to healthcare and industrial IoT with real-time AI. |
Frequently Asked Questions About On-Device SLM Deployment
What is on-device SLM deployment?▼On-device SLM deployment refers to running Small Language Models (SLMs) directly on local devices like smartphones or edge hardware, without needing cloud connectivity. This enables immediate processing, enhanced privacy, and reliable AI functionality even offline, revolutionizing AI accessibility.
How can a 70-billion parameter model run offline?▼Running a 70-billion parameter model offline is made possible through advanced quantization techniques. These methods reduce the model's memory footprint and computational demands by converting high-precision numbers (e.g., 32-bit floats) to lower-precision integers (e.g., 8-bit), allowing it to fit and operate efficiently on device hardware.
What are the main benefits of offline AI deployment?▼The primary benefits include significantly reduced latency due to local processing, enhanced data privacy as information stays on the device, improved reliability independent of internet connectivity, and potentially lower operational costs by minimizing cloud resource usage. It offers a more secure and responsive AI experience.
What role does quantization play in this technology?▼Quantization is crucial; it's the process of compressing neural network models by reducing the precision of their weights and activations. This dramatically shrinks the model's size and computational requirements, making it feasible to deploy extremely large models, like those with 70 billion parameters, on resource-constrained edge devices.
Which industries will be most impacted by on-device SLM deployment?▼Industries such as consumer electronics (smartphones, wearables), automotive (autonomous vehicles), industrial IoT (smart factories), and healthcare (portable diagnostics) are set to be profoundly impacted. These sectors benefit immensely from real-time processing, enhanced privacy, and reliable AI operations without cloud dependency.
Conclusion
The advent of on-device SLM deployment, especially the capability to run 70-billion parameter quantized models completely offline, marks a pivotal moment in the evolution of artificial intelligence. This technological leap transcends mere efficiency gains; it fundamentally redefines the accessibility, privacy, and responsiveness of AI. By moving intelligence to the very edge of our networks, we are not only overcoming traditional limitations of latency and connectivity but also ushering in an era where advanced AI is more secure, personal, and ubiquitous than ever before. The ongoing innovations in quantization, hardware acceleration, and software optimization promise a future where powerful AI seamlessly integrates into our daily lives, empowering devices to think and act autonomously, securely, and instantly.
